
Introducing BlenderBench
BlenderBench tests 20 Blender workflows, not just modeling. Some tasks supply a finished scene and ask for lighting or camera work. Others provide a character to rig or animate; a few require building geometry. Each brief defines what the agent receives, what it must change and what it must preserve.
Model results
GPT-6 Astra and Claude Opus 5.5 take on the same 20 tasks, from scene construction and materials to rigging, animation and simulation. The charts use all 40 reviewed results.
Mean reward across 20 tasks
40 reviewed resultsCost
Cost vs performance
20 matched tasks · estimated| Model | Mean reward | Total cost | Per task |
|---|---|---|---|
| GPT-6 Astra | 0.686 | $55.23 | $2.76 |
| Claude Opus 5.5 | 0.642 | $20.54 | $1.03 |
Results by task
- GPT-6 Astra
- Claude Opus 5.5
Mean reward by task type, not a pass rate. Expand for task scores, trajectories and saved outputs.
Modeling / scene construction3 tasks · Opus leadsGPT-6 Astra mean reward: 0.516Claude Opus 5.5 mean reward: 0.665
| Task | GPT-6 Astra | Claude Opus 5.5 |
|---|---|---|
Jewelry box composition
| 0.98Meets 0.90 threshold | 0.95Meets 0.90 threshold |
Mid century lounge chair model
| 0.00Below 0.90 threshold | 0.32Below 0.90 threshold |
Product cyclorama
| 0.57Below 0.90 threshold | 0.72Below 0.90 threshold |
Rigging2 tasks · Astra leadsGPT-6 Astra mean reward: 0.930Claude Opus 5.5 mean reward: 0.623
| Task | GPT-6 Astra | Claude Opus 5.5 |
|---|---|---|
Bicycle courier humanoid rigging
| 0.92Meets 0.90 threshold | 0.85Below 0.90 threshold |
Ring box rig and animation
| 0.95Meets 0.90 threshold | 0.40Below 0.90 threshold |
Animation6 tasks · Astra leadsGPT-6 Astra mean reward: 0.534Claude Opus 5.5 mean reward: 0.499
| Task | GPT-6 Astra | Claude Opus 5.5 |
|---|---|---|
Abyssal Explorer Animation
| 0.30Below 0.90 threshold | 0.30Below 0.90 threshold |
Cowboy defensive combat
| 0.52Below 0.90 threshold | 0.45Below 0.90 threshold |
Cowboy tightrope balance
| 0.40Below 0.90 threshold | 0.40Below 0.90 threshold |
Guardian boxing
| 0.40Below 0.90 threshold | 0.40Below 0.90 threshold |
Hazmat retreat and escape
| 0.58Below 0.90 threshold | 0.45Below 0.90 threshold |
Skeleton neutral pose run up
| 1.00Meets 0.90 threshold | 1.00Meets 0.90 threshold |
Camera / cinematics1 task · Astra leadsGPT-6 Astra mean reward: 0.948Claude Opus 5.5 mean reward: 0.824
| Task | GPT-6 Astra | Claude Opus 5.5 |
|---|---|---|
Camera animation
| 0.95Meets 0.90 threshold | 0.82Below 0.90 threshold |
Materials / surfacing1 task · Astra leadsGPT-6 Astra mean reward: 0.858Claude Opus 5.5 mean reward: 0.780
| Task | GPT-6 Astra | Claude Opus 5.5 |
|---|---|---|
Jewelry box surfacing
| 0.86Below 0.90 threshold | 0.78Below 0.90 threshold |
Lighting / reflections1 task · Astra leadsGPT-6 Astra mean reward: 0.934Claude Opus 5.5 mean reward: 0.756
| Task | GPT-6 Astra | Claude Opus 5.5 |
|---|---|---|
Apartment dining table set lighting
| 0.93Meets 0.90 threshold | 0.76Below 0.90 threshold |
Complete production1 task · Astra leadsGPT-6 Astra mean reward: 0.644Claude Opus 5.5 mean reward: 0.529
| Task | GPT-6 Astra | Claude Opus 5.5 |
|---|---|---|
Apartment Dining Table Set Complete
| 0.64Below 0.90 threshold | 0.53Below 0.90 threshold |
Garment retopology / UVs2 tasks · Astra leadsGPT-6 Astra mean reward: 0.917Claude Opus 5.5 mean reward: 0.735
| Task | GPT-6 Astra | Claude Opus 5.5 |
|---|---|---|
Asymmetric Expedition Poncho Cloth Preparation
| 0.86Below 0.90 threshold | 0.50Below 0.90 threshold |
Cloth Preparation
| 0.97Meets 0.90 threshold | 0.97Meets 0.90 threshold |
Cloth simulation2 tasks · Opus leadsGPT-6 Astra mean reward: 0.546Claude Opus 5.5 mean reward: 0.734
| Task | GPT-6 Astra | Claude Opus 5.5 |
|---|---|---|
Pressure Pillow
| 0.89Below 0.90 threshold | 0.87Below 0.90 threshold |
Ring cloth pull
| 0.20Below 0.90 threshold | 0.60Below 0.90 threshold |
Hair dynamics1 task · Astra leadsGPT-6 Astra mean reward: 0.801Claude Opus 5.5 mean reward: 0.772
| Task | GPT-6 Astra | Claude Opus 5.5 |
|---|---|---|
Hair Dynamics
| 0.80Below 0.90 threshold | 0.77Below 0.90 threshold |
Mean solving time: GPT-6 Astra 14.0 minutes; Claude Opus 5.5 14.7 minutes (verification excluded).
Task coverage
We chose these 20 tasks from a larger library of expert-built and generated tasks, covering 10 types of work.
20 active tasks
- Animation630%
- Modeling / scene construction315%
- Rigging210%
- Garment retopology / UVs210%
- Cloth simulation210%
- Camera / cinematics15%
- Materials / surfacing15%
- Lighting / reflections15%
- Complete production15%
- Hair dynamics15%
20 retained tasks across 10 task types.
Score distributions
Each score range compares GPT-6 Astra with Claude Opus 5.5 across the same 20 tasks. Hover, focus, or select a bar to see which tasks it contains, along with their types, exact scores and trajectories.
How both models scored on 20 tasks
- GPT-6 Astra
- Claude Opus 5.5
| Score range | GPT-6 Astra | Claude Opus 5.5 |
|---|---|---|
| 0–0.25 | 2 | 0 |
| >0.25–0.50 | 3 | 8 |
| >0.50–0.75 | 4 | 3 |
| >0.75–1.00 | 11 | 9 |
| Total | 20 | 20 |
Task examples
Current benchmark / Rigging & animation
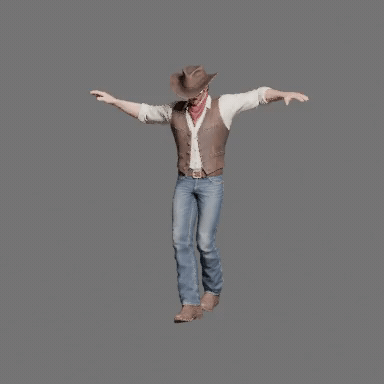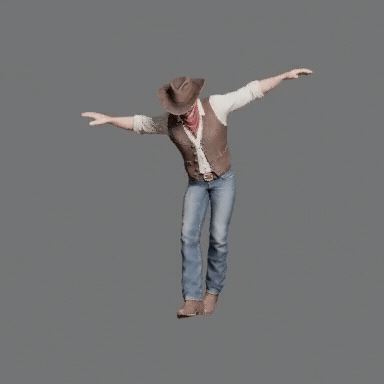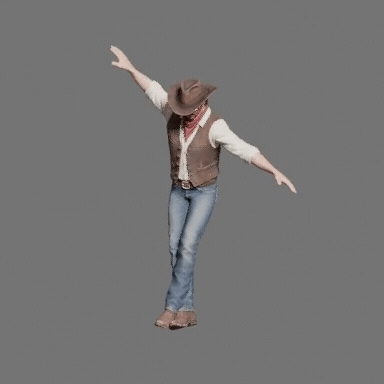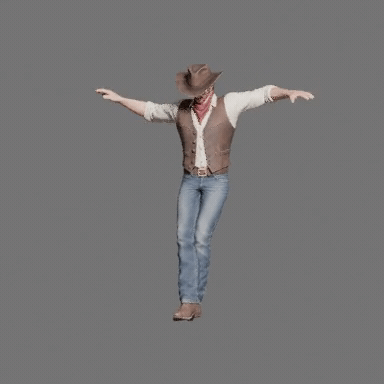
Cowboy tightrope balance
- Provided
- An unrigged cowboy mesh, materials and a balancing reference.
- Agent task
- Build and skin the rig, then animate the body and fingers. Preserve the mesh.
Task reference
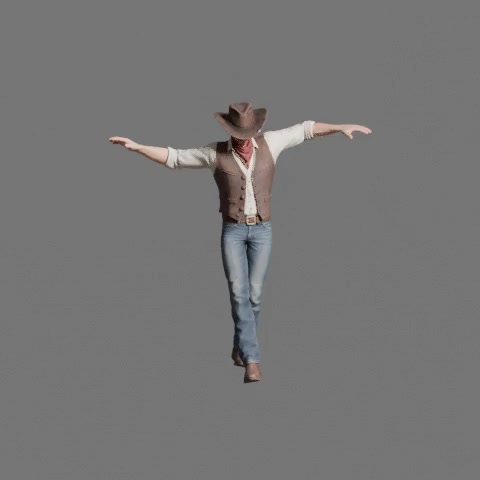
Reference motion.
Claude Opus 5.5
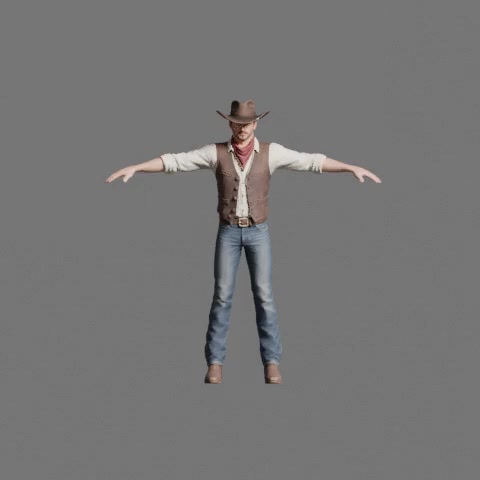
The judge found that the feet stayed planted instead of following the reference’s steps, while chest-joint placement triggered the verifier’s 0.400 cap.
Frames 1–126 at 24 fps; same fixed camera and lighting, no animation edits.
Fixed-camera previews isolate the character's motion. View a looping GIF of the task reference.
How the verifier scores this task
The verifier opens the saved Blender file, checks the rig and skinning built for the supplied cowboy, and compares the body and finger animation with the balancing reference. Five weighted sections add up to a score from 0 to 1. If it finds a serious problem, a cap sets the highest final reward allowed, whatever the weighted total.
| Section | Weight | Claude Opus 5.5 |
|---|---|---|
| Rig qualitySkeleton and skinning built for the supplied mesh | 20% | 0.135 |
| Body animationThe body's balancing motion | 20% | 0.073 |
| Hand animationFinger and hand motion | 15% | 0.084 |
| Reference fidelityMatch to the reference; numeric checks and model-based visual assessment count equally | 40% | 0.163 |
| PreservationThe supplied mesh left intact | 5% | 0.050 |
| Weighted total | 100% | 0.504 |
| Cap | Highest reward | Recorded |
|---|---|---|
| Skeleton qualityJoints placed away from the anatomy | 0.40 | Yes |
| Severe anatomySevere damage to the character's anatomy | 0.40 | Yes |
| Low fidelityMotion departs from the reference | 0.60 | Yes |
| Very low fidelityMotion departs far from the reference | 0.40 | No |
Grooming & dynamics
Hair dynamics
- Provided
- A head mesh, skin material, camera, lights and hair references.
- Agent task
- Create and groom swept-back hair, then simulate its motion. Preserve the head.
Task reference
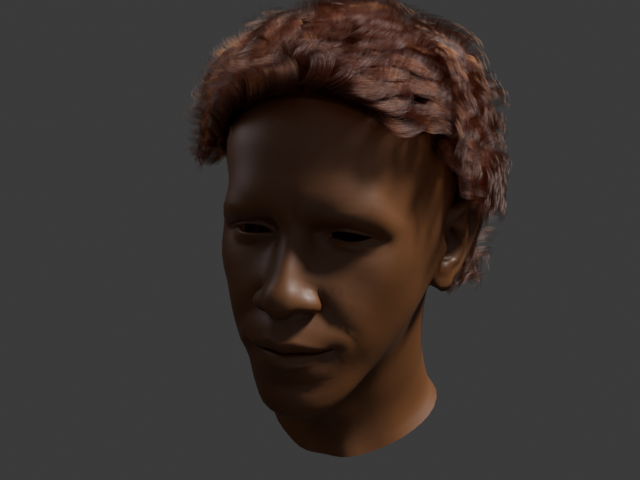
Supplied task reference. Select a frame to inspect.
GPT-6 Astra
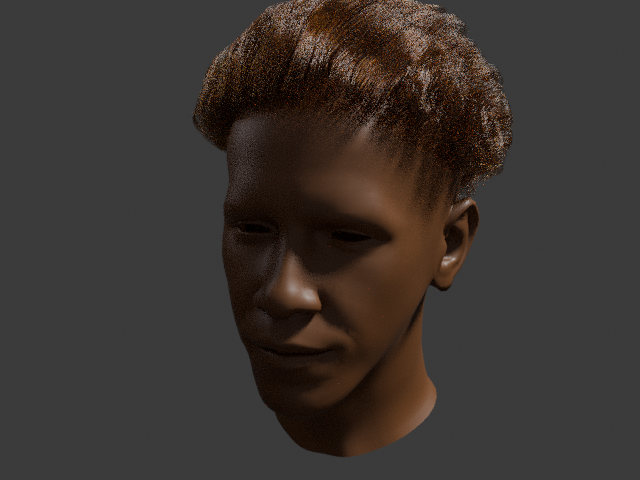
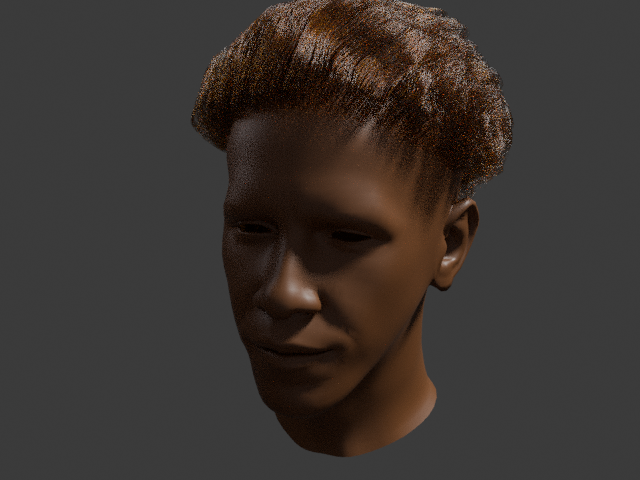
The judge found that the tidy groom lacked the reference’s distinct curls and side coverage and barely moved between frames, lowering the final reward to 0.801.
Claude Opus 5
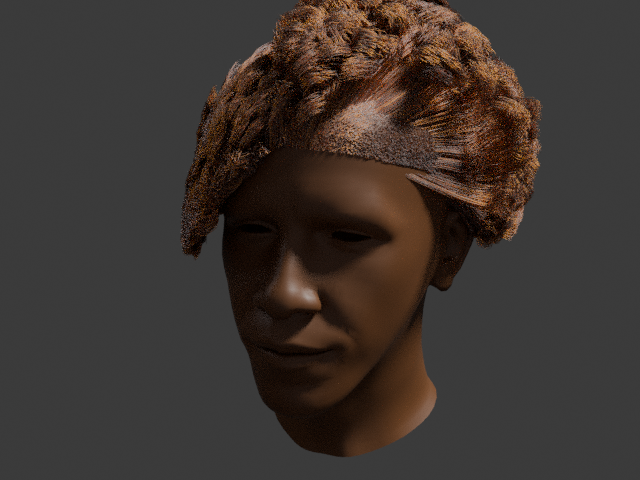
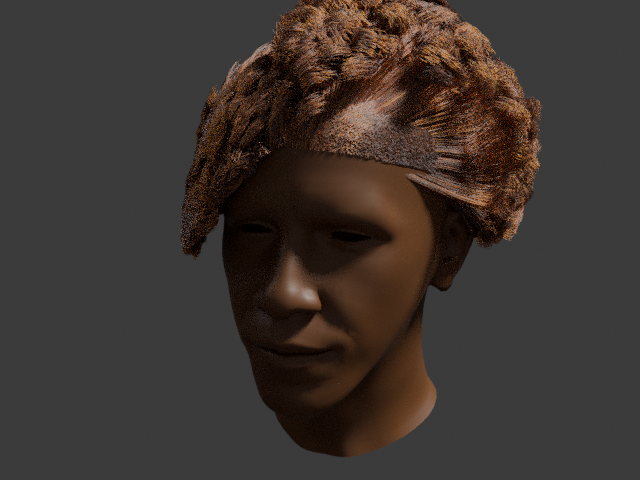
Earlier Opus 5 run, outside the 20-task comparison.
Gaps between the hair and scalp, a hard hairline and hair covering the ear accompanied a 0.38 visual score, with a weak-material cap limiting the final reward to 0.60.
Retained frames 1 and 30; a continuous animation is not available for this comparison. Download Opus 5 static 3D preview (frame 30, simplified hair material).
Where the hair falls short
GPT-6 Astra · verifier blender-v1.27.0
| Final reward | 0.801 |
|---|---|
| Points lost | 0.199 |
| Lost by areaThe release records this run's final reward, not its per-area scores. | Not recorded |
The recorded review found curls and side coverage that lag the reference.
Claude Opus 5, earlier run · verifier blender-v1.19.0
| Area | Weight | Earned | Lost |
|---|---|---|---|
| Visual assessmentModel-based comparison of the rendered frames with the reference | 35% | 0.133 | 0.217 |
| Hair materialShading of the hair strands | 6.5% | 0.042 | 0.023 |
| Scalp fitHow closely the groom sits on the head | 13% | 0.119 | 0.011 |
| Scene preservationSupplied head, camera and lights left intact | 9.75% | 0.098 | 0.000 |
| Hair system setupThe required hair system is present | 9.75% | 0.098 | 0.000 |
| Dynamics and collisionHair simulation and collision with the head | 13% | 0.130 | 0.000 |
| Render provenanceFrames rendered from the saved scene | 13% | 0.130 | 0.000 |
| Weighted total | 100% | 0.750 | 0.250 |
| Weak hair material cap | 0.600 | 0.400 |
Cloth simulation
Ring cloth pull
- Provided
- Cloth, ring, diamond and table meshes, plus a velvet render mesh.
- Agent task
- Set up cloth simulation and pull the cloth through the ring.
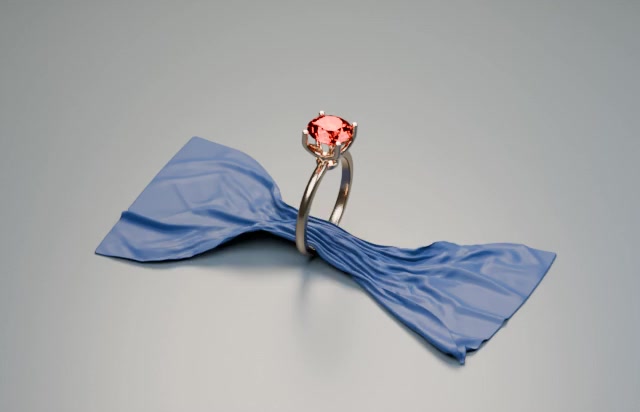
Reference scene
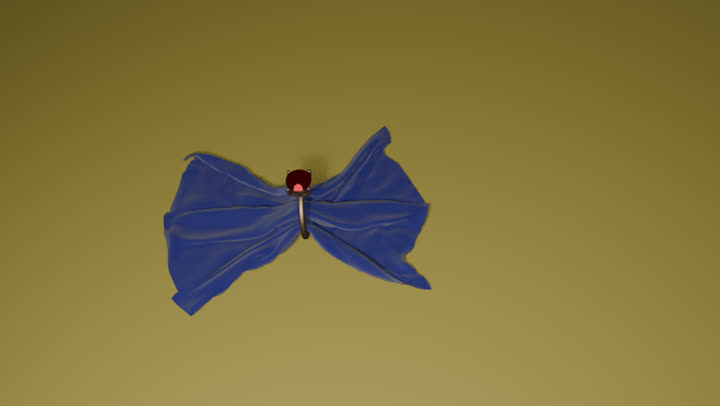
Animation of the scene the task was built from. Agents received the linked target image.
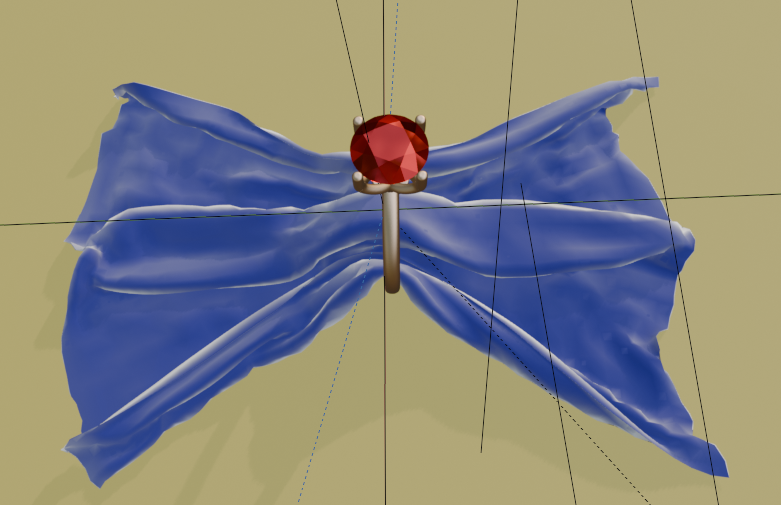
GPT-6 Astra
Changes to the protected ring and diamond, plus an altered backdrop, triggered the verifier’s 0.20 scene-preservation cap, despite passing its cloth-solver checks.
Claude Opus 5.5
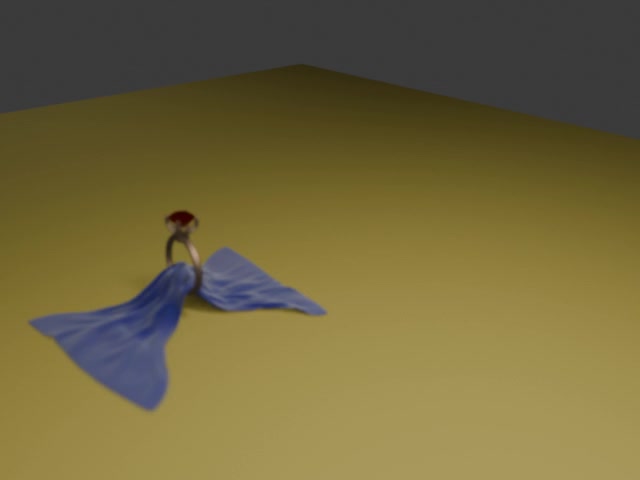
The judge found that the cloth stayed bunched instead of spreading roughly flat after clearing the ring, while a reference-shape mismatch capped the reward at 0.60.
Scoring methodology
Each task has a versioned verifier. It checks the saved Blender file against the brief, confirms that protected parts of the starting scene remain intact, and compares rendered frames or clips with the references. It uses numeric checks and, where specified, model-based visual assessment.
The task's rubric turns these checks into a reward from 0 to 1, with partial credit for completed requirements. Weights, validity gates and any caps depend on the task. You can inspect the saved outputs, evaluation records and verifier identities.
Evaluate with BlenderBench
We're adding tasks in modeling, materials, rigging, animation, lighting and simulation. We can work with your team to evaluate agents in a consistent environment and review the saved scenes, trajectories and task-specific scores. Longer term, we want these tasks to support reinforcement learning across an entire animation workflow.
To arrange an evaluation, email contact@refresh.dev. We can discuss task coverage and difficulty, along with the environments and tools your agents use.